RELEASE HIGHLIGHTS
Lots of Quality of Life improvements in this release, as well as some long-awaited enhancements to our Code IQ code exploration agent.
CODE IQ
Code IQ agent enhancements
We launched Code IQ in 2025 as our embedded code exploration agent, that can answer any query about a codebase the same way a senior engineer or CTO would.
Since then we’ve had various requests to add features or improvements to it, and we’re happy to say they are all included in this release!
The ability to organize Code IQ queries into folders
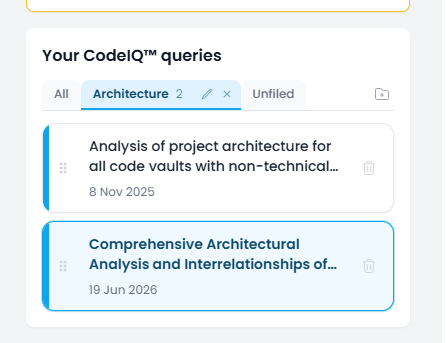
You can now organize Code IQ queries into custom folders to help manage them.
Upgrade the underlying model used for automated Code IQ queries
This has been a popular request! Code IQ queries can be varied and complex, and often users can be left with additional questions or clarifications that they need to discuss.
Previously you’d need to ask separate new Code IQ queries to explore those additional bits, but now you can simply ask follow-on questions. Code IQ will do fresh web research and code exploration if needed, as well as review the contents of the current report to answer those fresh queries.
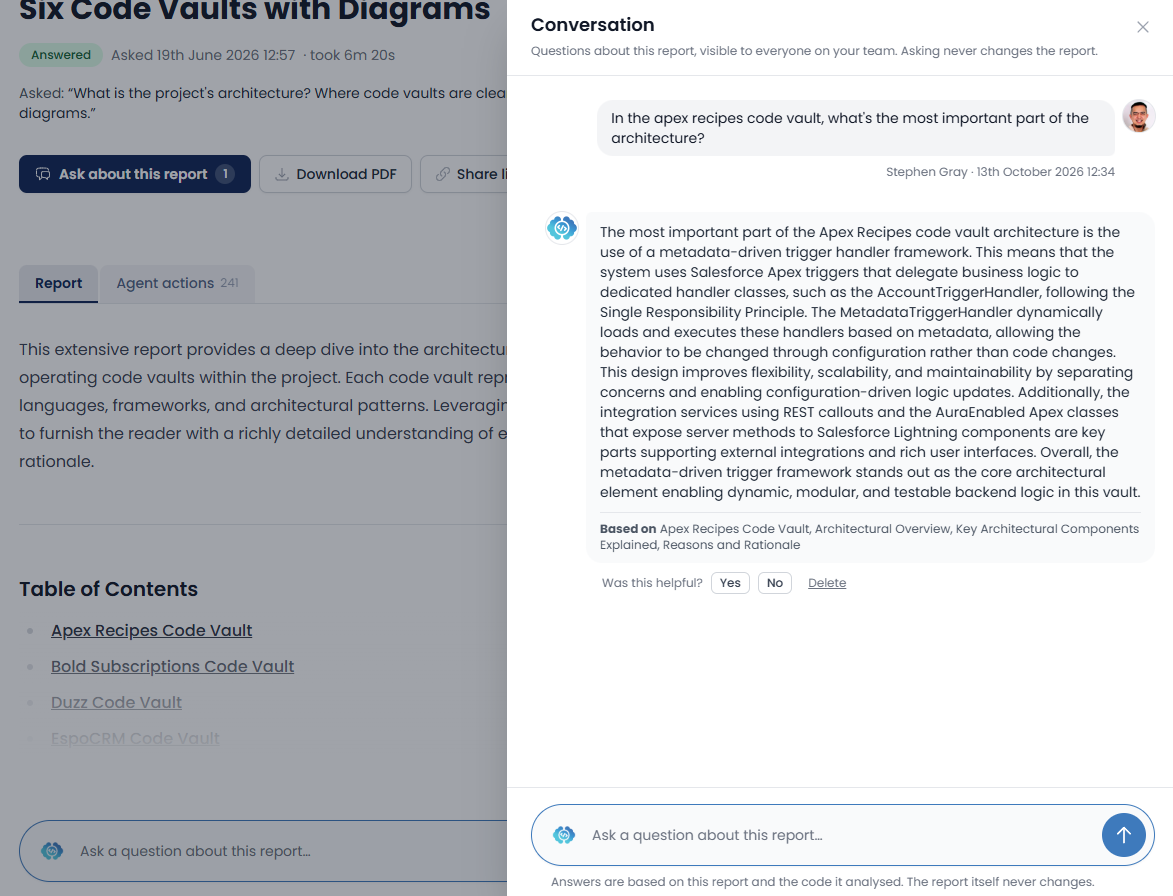
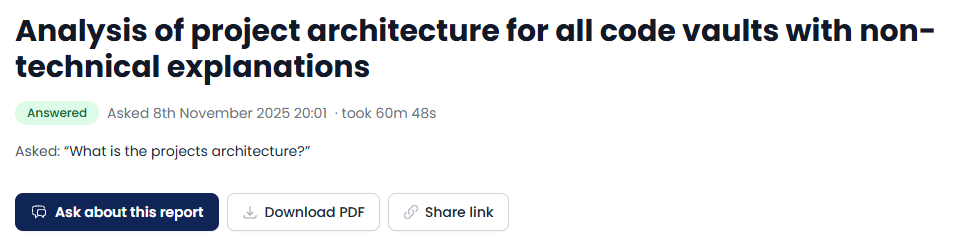
The ability to share Code IQ reports as a PDF or URL
You can now download any Code IQ report as a PDF, or generate a publicly available URL to share with anyone that needs it.
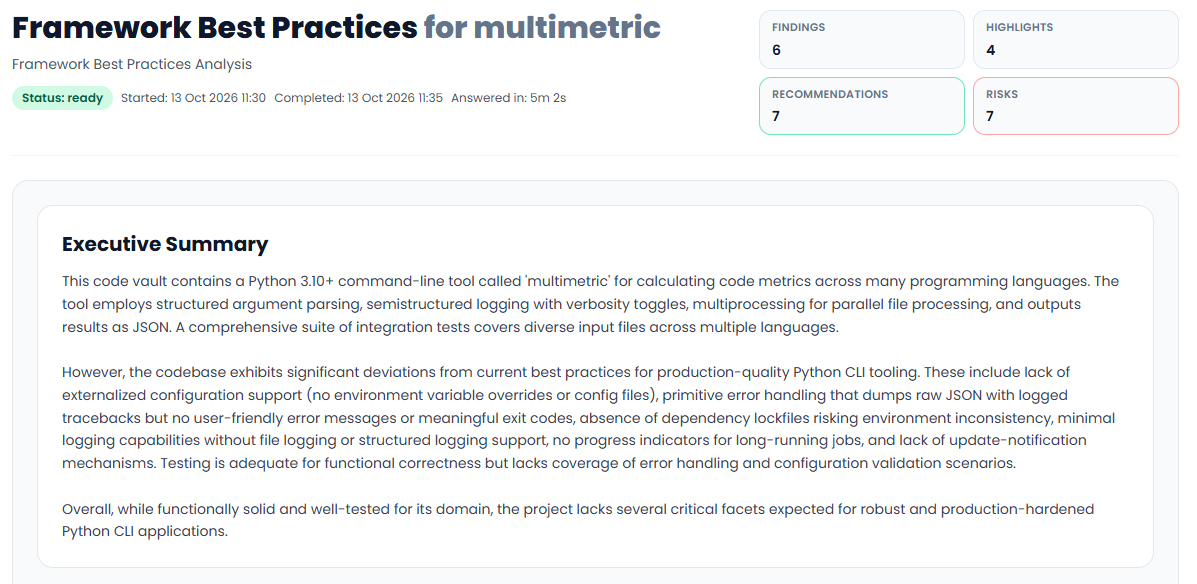
New automated query for every codebase: Framework Best Practises
The Code Registry already triggered automated Code IQ queries for every codebase analysed: Scalability, Architecture, Detected AI functionality and End of Life technologies.
We’ve now expanded this into Framework Best Practises. If Code IQ can see that your code is using a framework, such as PHP Laravel or Python Django, it will do web research around that framework’s best practises, and then explore your code to see if they’re being followed
Up until now, the automated queries were using a “nano” model, primarily because we wanted these automated queries to be quick and ready as soon as you start browsing the platform.
We continually weigh up the quality of the results and code exploration verses the cost to us as a business, and in a sample of latest results, the quality of the automated queries was not good enough.
Automated queries now use a larger flagship model behind the scenes and we’re already seeing much deeper, better results.
OTHER CHANGES
Allow for anonymous / public repos
We had feedback that it should be easier to analyze public repositories, and not need to enter GitHub authentication to do so. There’s now a checkbox to say if a repo being analysed is public or not.
Improve support for Apple Silicon Mac devices in our Local Code Agent
These specific architecture devices were having issues running our local code agent to analyze code on their machines
Make it easier to find our MCP server and API docs
We’ve updated the platform UI a bit to make this easier to find in the sidebar menu
Update the file ignore rules in our security and opensource dependency analysis
There were some package configuration files being ignored or not parsed properly, and some folders that were being analysed and shouldn’t have been. For example .git/HEAD files!
In our opensource dependency analysis, don’t assume a blank version is the latest version
In our opensource dependency analysis, if we analysed a package configuration file like a lockfile, and there was a blank version, it was assumed that the installed version must be the latest version. But this was too optimistic and in most cases, this won’t be true. This is now adjusted.
BUG FIXES
- Fixed an issue where in some cases, triaged security issues were ignored by the Code Score calculation
- Fixed a bug where triaged security issues could lose their issue status after the next code sync
- Fixed a bug at the single code vault level where in some cases a stale Code Score calculation was shown instead of the latest one
- Fixed an issue stopping the Microsoft SSO login from working
- Fixed an issue where team invites invalidated too quickly causing them to not work
- Fixed a bug where older Local Code Agent data archives could be imported for a project over newer ones
- Fixed broken images in some email templates sent from the platform due to an old CDN URL
- Fix some bugs in retrieving the full data sets via the API and MCP server in some cases
- Improved the retry when retrieving file contents in the platform embedded code browser
- Improve UTF8 encoding issues and error handling in the embedded platform code browser
- Fixed a UI issue so the opensource components page doesn’t change the page scroll position when filtering outdated components
- Fixed a bug on single code vault view in some GIT related widgets not displaying properly